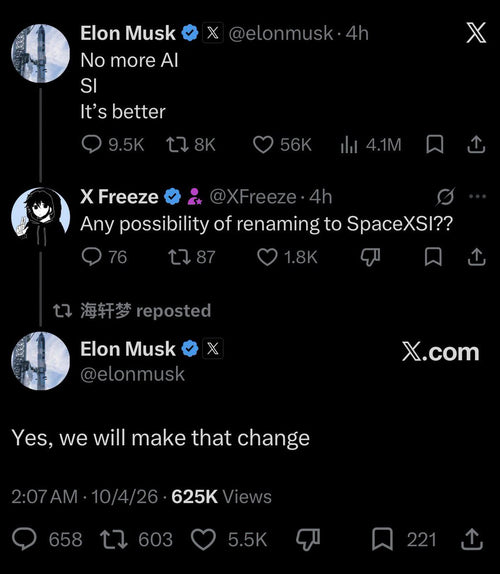

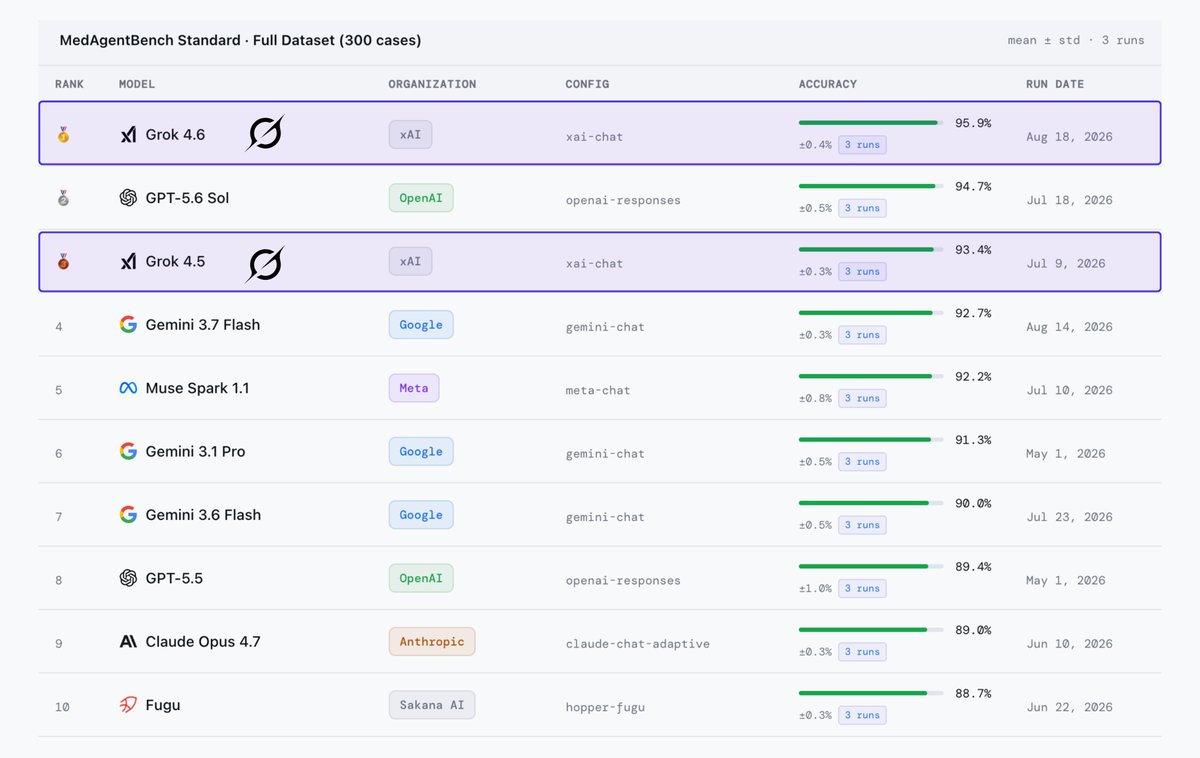
Grok just claimed a significant benchmark. Elon Musk announced Tuesday that Grok 4.6 has reached the top spot for answering healthcare-related questions — a domain where accuracy isn't just a nice-to-have, it's the whole ballgame.

The claim comes without a named benchmark in the tweet itself, so the specific leaderboard or evaluation dataset behind the ranking isn't independently verifiable from this announcement alone. That said, healthcare is one of the most closely watched categories in AI evaluation — it typically involves clinical reasoning, drug interaction knowledge, diagnostic accuracy, and the ability to flag when a question exceeds what an AI should answer without a professional. A top ranking there carries more weight than many general-purpose benchmarks.
Grok 4.6 is the latest iteration of xAI's flagship model, and this marks a notable step in positioning it as a domain-specific tool rather than just a general-purpose assistant. Whether that translates into real-world utility for patients, clinicians, or researchers will depend on how the model handles edge cases — but the benchmark claim puts Grok in a conversation it wasn't leading even a few months ago.
Sources & reporting notes
The links below identify the material source records used for this report.
- @elonmusk on X (2026-08-19T14:07:40.000Z) — Direct source
Source links are preserved as published or accessed. See our editorial standards and corrections policy.
The BASENOR Editorial Desk covers Tesla, SpaceX, and related technology, curating reporting from primary sources — official accounts, regulatory filings, and software release data. Every article passes source-record and fact-checking review before publication. About the newsroom.
This report was curated by the BASENOR Editorial Desk from the sources listed above. Read our editorial standards or email editorial@basenor.com to report an error.